
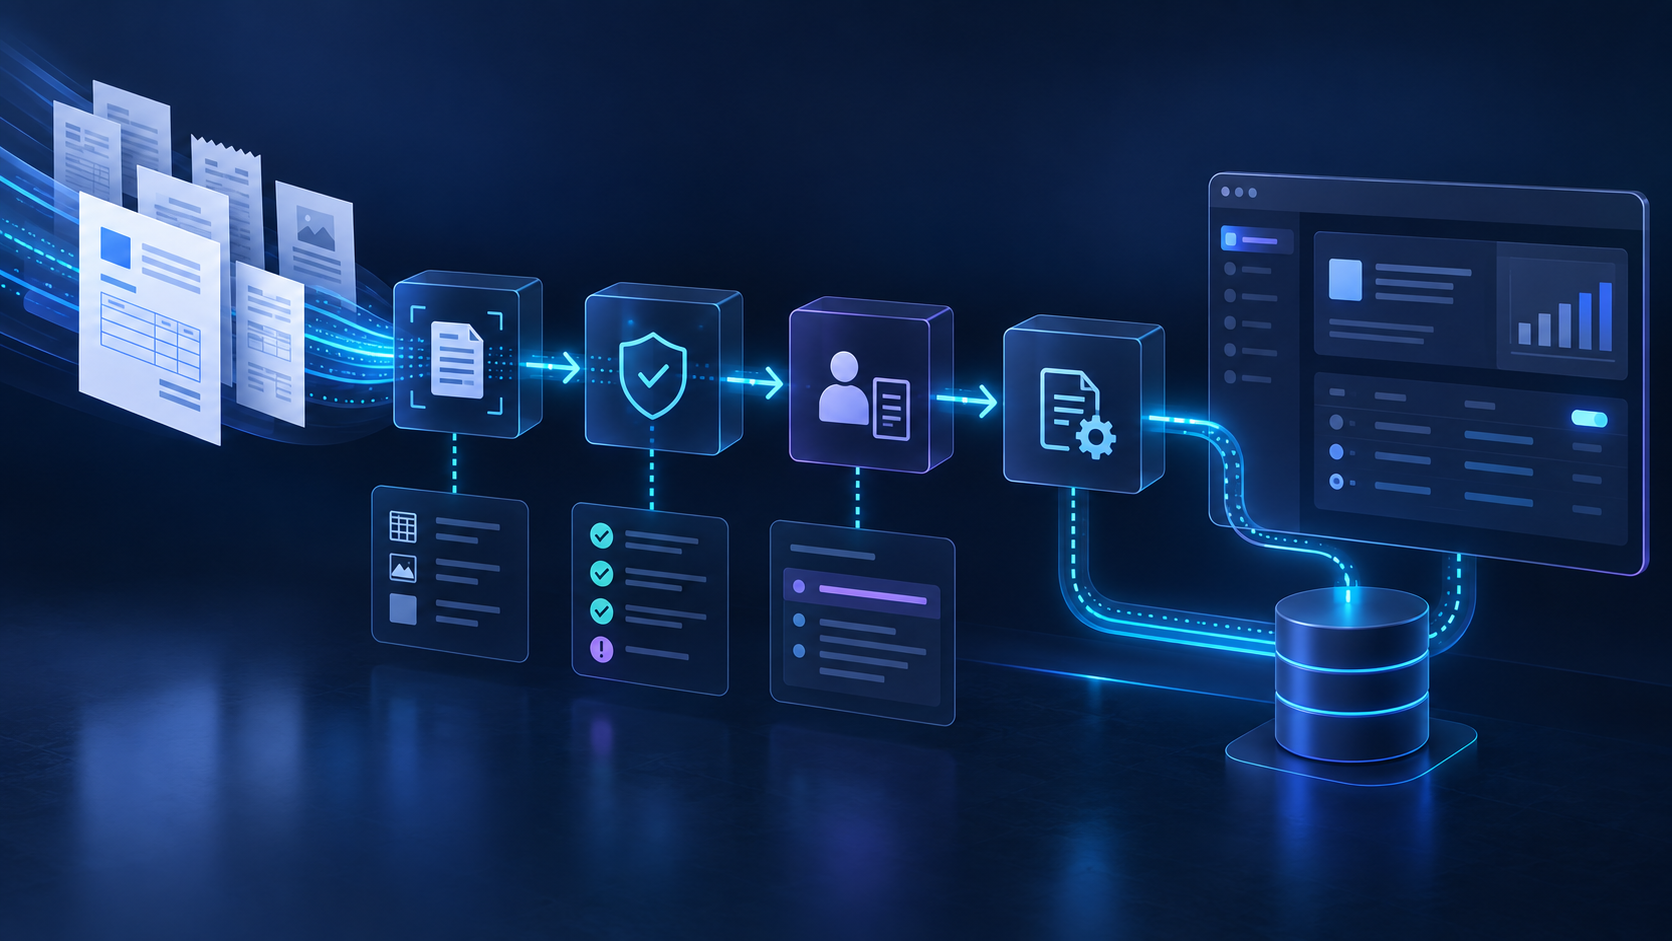
Build an document workflows with 6 essential checks for ingestion, extraction, validation, permissions, human review and traceable product updates. This guide explains the decisions, implementation boundaries and review points that matter inside an established product.
Table of Contents
document workflows: a practical overview
Building Intelligent Document Workflows Into SaaS Products is a practical question for established B2B SaaS teams that already have customers, workflows, APIs, data and permission rules. The useful answer is not a list of model capabilities. It is a way to improve a real product task while keeping the surrounding software understandable, secure and supportable. This guide focuses on the decisions a product and engineering team can make before the feature reaches customers.
Documents are rarely the whole workflow
The useful question is not whether a model can read a PDF. It is what the product should do with the information afterward. Map the document into the real business process. Define whether the output is fields, clauses, a summary, risk flags or routing. That sounds simple, but the decision has to make sense inside the normal product workflow, not only in a demo. The team should be able to explain who benefits, what changes for that user and which existing product boundary remains in control.
Identify where human review belongs. Measure the full workflow rather than extraction alone. For teams with real customers and production data, this affects the API boundary, test cases, support path and what the user sees when something goes wrong. Making that choice explicit early reduces rework and gives product and engineering a shared standard for the first release. A questionnaire may need extraction, evidence checks, policy comparison and a reviewer decision. Before moving on, check whether the behavior can be reproduced with representative product data and a real permission context.
Start with document classes and outcomes
Different business documents need different handling even when they share the same file format. List the actual document types the product receives. Define the expected structured or narrative output for each class. The important point is that the decision has to make sense inside the normal product workflow, not only in a demo.
Separate low-risk auto-accept fields from review-required fields. Avoid a promise to “understand any document.” For a mature SaaS product, this affects the API boundary, test cases, support path and what the user sees when something goes wrong. A supplier questionnaire and a signed contract may both be PDFs but have very different acceptance rules. A simple way to check this is to ask the behavior can be reproduced with representative product data and a real permission context.
Build a reliable ingestion path
Document AI starts with ordinary file handling. Use stable file identifiers and tenant ownership. Apply supported format and size limits. This matters because the decision has to make sense inside the normal product workflow, not only in a demo.
Use OCR or document vision for scanned files when needed. Track processing status and failures for asynchronous work. In an established product, this affects the API boundary, test cases, support path and what the user sees when something goes wrong. The original file should remain in the system that already owns it. The practical check is the behavior can be reproduced with representative product data and a real permission context.
Keep derived data linked to the source
Text, chunks and embeddings are derived product data and need a lifecycle. Link every derived artifact to the source document. Keep freshness rules when documents are replaced. The reason is straightforward: the decision has to make sense inside the normal product workflow, not only in a demo.
Honor deletion and retention requirements. Carry tenant and access metadata into indexes. Inside an existing SaaS product, this affects the API boundary, test cases, support path and what the user sees when something goes wrong. A removed document should not remain searchable through an old vector entry. A useful test is to ask the behavior can be reproduced with representative product data and a real permission context.
Choose the right extraction method
Not every field needs a large language model. Use deterministic parsers for stable formats. Use OCR and layout-aware methods when structure matters.
Use LLMs for variable language or interpretation. Combine methods when a hybrid approach is clearer and cheaper. A stable invoice number may be parsed deterministically while a contract clause needs semantic interpretation.
Return structured output
Schemas make document results easier to validate and save. Define required fields and types. Include source location and confidence or review flags where useful.
Reject malformed output before it touches product state. Keep narrative summaries separate from structured fields. For a mature SaaS product, this affects the API boundary, test cases, support path and what the user sees when something goes wrong. A field with amount, currency and source page is easier to validate than a paragraph containing all three.
Keep source references visible
Reviewers need to see where important information came from. Store page, section or region references when available. Let users open the source from the review screen.
Mark inference separately from extracted fact. Use source links to speed correction and support. Traceability turns review from guesswork into a quick verification step.
Design human review as part of the product
Human-in-the-loop should target uncertainty and consequence rather than require manual checking forever. Auto-accept high-confidence low-risk fields only when policy allows it. Route uncertain or high-impact items to review.
Show the proposed value and evidence together. Capture corrections as useful evaluation examples. If users spend longer checking AI output than entering the data manually, the workflow has not improved.
Validate against product rules
The model interprets; the product decides whether the result is valid. Check dates, codes, ranges and required relationships in normal code. Compare extracted values with existing product state.
Flag conflicts rather than silently overwriting data. Keep policy deterministic when possible. A supplier identifier should match a valid supplier in the authenticated tenant before it is saved.
Evaluate by consequence, not one accuracy score
A single average hides the fields that matter most. Build evaluation sets for each document class. Include poor scans, missing pages and unusual layouts.
Score critical fields separately from low-consequence fields. Measure review time and correction rate as product outcomes. A wrong termination date can matter more than several minor formatting errors.
A practical example
Vendor security questionnaires show how document AI becomes a workflow feature. Classify the questionnaire and extract answers. Link answers to source locations.
Flag missing evidence and policy exceptions. Keep final vendor approval with the reviewer. The value is a faster, more consistent review process, not simply “the AI read the document.” The practical check is the behavior can be reproduced with representative product data and a real permission context.
Common document AI mistakes
Lifecycle and review design are common blind spots. Do not treat every PDF as the same problem. Do not discard source structure too early.
Do not write extracted values directly into product state without validation policy. Do not ignore permission changes and deletion in derived stores. Production document AI is a data-governance feature as much as a model feature.
document workflows: frequently asked questions
Do we need OCR before using an LLM?
For scanned or image-based documents, usually yes. The system needs usable text or structure before later interpretation can be dependable.
Should extracted fields be saved automatically?
Only when risk is low, validation is strong and product policy allows it. Many workflows benefit from review.
How do we keep document AI permission-aware?
Carry tenant and access metadata through derived stores, enforce authorization at retrieval and remove derived access when the source changes.
document workflows: final takeaway
Building Intelligent Document Workflows Into SaaS Products becomes much easier to plan when the team keeps one real user workflow at the centre of the design. Use the existing product boundaries, make quality measurable and keep the first release narrow enough to understand end to end. That is a more dependable route to production than adding a broad assistant and hoping customers discover the value on their own.
Machine Minds works with established B2B SaaS teams on this kind of bounded AI feature development: shaping the workflow, integrating with real product context, building evaluation and taking the capability through a controlled release. The next step should be based on the evidence from that first feature, not on a generic AI roadmap.
document workflows: further reading and next steps
For a complementary approach to trustworthy AI design, evaluation and ongoing oversight, explore the NIST AI Risk Management Framework. Apply those principles alongside your product’s existing authorization, testing and release controls.
Explore Machine Minds AI Product Engineering and the AI Feature Sprint, or discuss your product workflow with the team.
When planning document workflows, keep the scope tied to one measurable customer task. Review document workflows with engineering and support before expanding the release.
